Shipped: Split AI Capabilities Into Independent Grading Modules
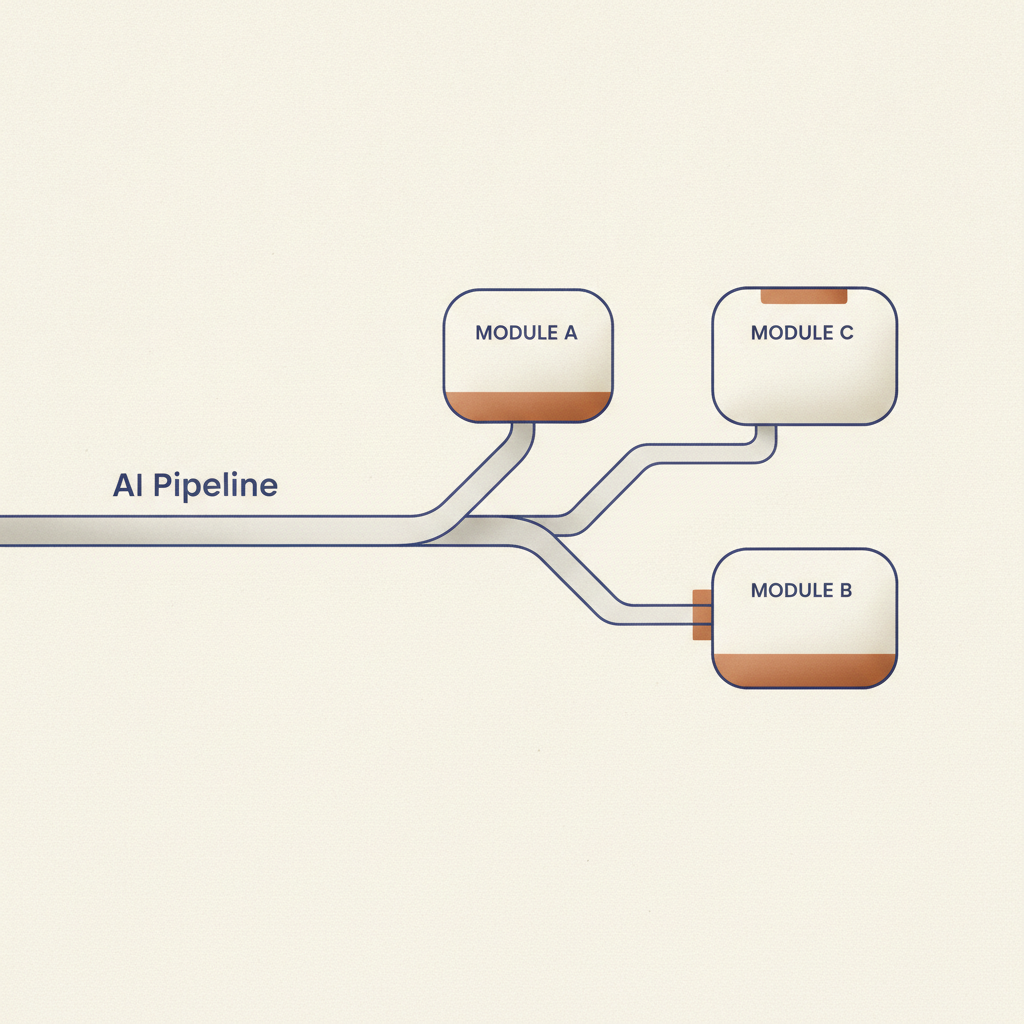
Splitting AI capabilities into independent grading modules means areturnz now runs condition grading, content verification, and quantity verification as three separate AI passes instead of one bundled pipeline, each producing its own confidence score, its own tag set, and its own webhook event. The change ships across the network today and touches every return processed at NJ-01, including the 180K+ already run through the system.
If you have been reading the changelog, you already know the building blocks: photo evidence on every parcel, then AI content and quantity verification on receiving. This release does not add a new capability so much as it reorganizes the ones we already had, and that reorganization turns out to matter more than it sounds.
What changed
Before this release, a return moving through receiving got one combined AI pass. The model looked at the outer label photo, the opened-parcel photo, the item photo, and the defect photo, then returned a single bundle: a condition grade (A, B, C, or R), a content verification result (right item, right variant), a quantity result (units expected vs units received), and one confidence score covering the whole bundle.
That worked fine until a tenant wanted content verification but not full condition grading on a category where grading does not apply well, or wanted quantity verification turned off for single-unit SKUs where it never triggers anything useful. The bundle forced an all-or-nothing choice. Now each capability is its own module:
Condition grading module
Runs the ABCR model against the item and defect photos. Outputs a grade (A, B, C, R), a confidence score, and detected condition tags (scuffed, missing tag, opened box, and so on). This is the module described in detail in how AI condition grading actually works.
Content verification module
Compares the item in the opened-parcel photo against the order record to confirm the right product and variant came back. Outputs a match or mismatch result with its own confidence score, independent of whatever grade the item gets.
Quantity verification module
Counts units in the parcel against the expected unit count for multi-pack and bundle SKUs. Outputs a count result and flags shortages or overages for operator review.
Each module can be enabled or disabled per tenant, per category, or per SKU rule. A beauty brand that cares deeply about seal and fill-level condition but has no multi-unit SKUs can run condition grading and content verification while leaving quantity verification off entirely. A marketplace seller moving bundled accessory kits can run all three.
Why we split it
Three reasons pushed this change, and none of them were about accuracy for accuracy's sake.
First, speed. A bundled pass has to wait on the slowest module before it returns anything. Splitting the modules let the faster ones (content and quantity verification tend to resolve quicker than full condition grading) report back independently, which shaves real minutes off the 48 hour median cycle from inbound scan to disposition on high-volume days.
Second, configurability. Disposition rules route a return to restock, liquidate, donate, or destroy based on grade and confidence, but not every tenant weights condition, content match, and quantity the same way. Separating the modules lets a partner build a disposition rule that only escalates to human review when condition confidence is low, even if content and quantity both came back clean and confident.
Third, auditability. The 99.6% AI-vs-operator match accuracy number we publish is measured across the whole grading process, but operators reviewing a specific override now see which module triggered the review, not just a blended score they have to untangle by hand.
Module behavior at a glance
| Module | What it checks | Output | Can run independently |
|---|---|---|---|
| Condition grading | Item and defect photos against ABCR criteria | Grade (A/B/C/R), confidence score, condition tags | Yes |
| Content verification | Opened-parcel photo against order record | Match/mismatch, confidence score | Yes |
| Quantity verification | Unit count in parcel against expected count | Count result, shortage/overage flag | Yes |
| Combined bundle (legacy) | All three checks in a single pass | One blended result and confidence score | Deprecated for new tenants |
What this means for the API and dashboard
Each module now fires its own webhook event instead of one combined event, so integrations can subscribe to condition.graded, content.verified, and quantity.verified separately rather than parsing one payload for everything. The evidence bundle in the dashboard, and the same bundle available via signed-JSON API, now shows each module's result as its own card with its own confidence score and timestamp, which makes it easier to trace exactly which check an operator overrode and why. You can see the format of that evidence output firsthand at the evidence sample page.
Existing tenants on the combined bundle keep working exactly as before. Nothing breaks. New tenants and anyone who wants to reconfigure which modules apply to which categories can do it from the dashboard without a support ticket.
Rolling this into the bigger picture
This is one entry in a longer run of changelog work that keeps pushing more of the grading and receiving process into independently addressable pieces: granular API keys for partner integrations, real-time ops notifications on the receiving line, package lookup across the network, and now split AI modules. You can track all of it on the product updates hub, where each release gets the same treatment: what shipped, why, and what it changes for anyone running returns through the network.
Frequently asked questions
Does splitting the AI modules change the ABCR grading scale?
No. Condition grading still outputs A, B, C, or R with a confidence score attached. The grading logic itself did not change, only the way it is packaged and reported alongside content and quantity verification.
Will this slow down or speed up disposition?
It should speed things up on average, since faster modules no longer wait on slower ones before reporting results, which helps keep the 48 hour median cycle from inbound scan to disposition on track during high-volume periods.
Can I turn off content or quantity verification for specific SKUs?
Yes. Each module can be enabled or disabled per tenant, per category, or per SKU rule from the dashboard. A category with no multi-unit SKUs, for example, does not need quantity verification running at all.
What happens to tenants still on the combined bundle?
Nothing changes for them automatically. The combined bundle is deprecated for new tenants but existing integrations keep receiving the same blended output until they choose to move to the split modules.
Where do I see the per-module confidence scores?
In the dashboard evidence bundle and via the signed-JSON API, each module now reports its own confidence score and timestamp instead of one blended figure for the whole AI pass.
Questions about moving your integration onto the split modules, or want to see how disposition rules change with per-module confidence scores? Talk to us.
Related reading: Shipped: encrypted session storage for returns data security